Code-Mixed and Multilingual Information Retrieval
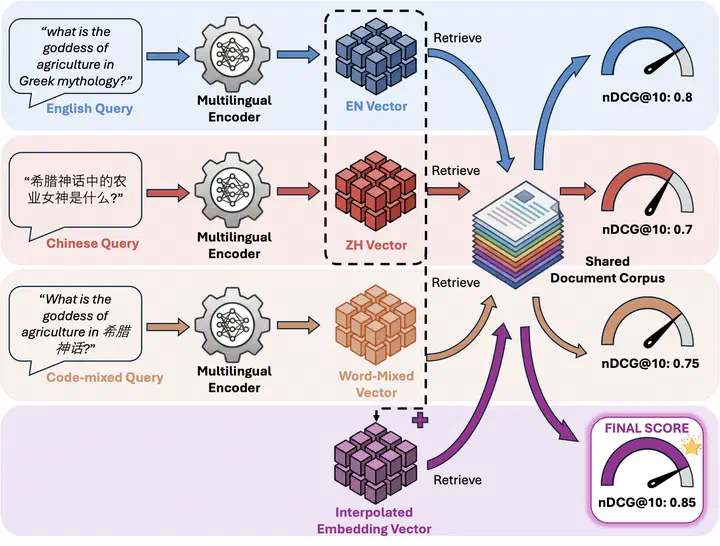 Monolingual, word-mixed, and embedding-mixed query representations retrieving from a shared document corpus.
Multilingual users often mix languages in real search queries, but dense retrievers are usually evaluated on monolingual ones. This project studies retrieval with code-mixed and mixed-language queries: what happens when the query representation itself is mixed, and when combining languages in a query actually helps retrieval.
In When Does Mixing Help? Analyzing Query Embedding Interpolation in Multilingual Dense Retrieval (ACL 2026, oral), we run a ratio-controlled study of mixed-language querying on mMARCO. Given two parallel query translations, we encode both, interpolate their embeddings at a controlled mixing ratio, and retrieve with the normalized mixture. Across 35 language pairs, each with three document-language settings, the best mixed query embedding from BGE-M3 beats the better monolingual endpoint in 88 of 105 settings. The gains are asymmetric and driven by English dominance: mixing helps for non-English document indices, while indices containing English are best served by pure English queries. After controlling for English dominance, larger typological distance between the two languages is associated with smaller mixing gains. The query-embedding-mix repository provides the code and result tables, and the word-mixed query sets are released on Hugging Face.
Tongyao Zhu
IPP Doctoral Student (Jan ‘23; SEA)
Co-Supervised by Qian Liu.
Research Achievement Award (RAA, ‘25)
PhD Candidate January 2023 Intake
Chao Ming Huang
FYP Alumnus (Apr ‘26). Thesis: Evaluating and Enhancing Information Retrieval in Code Mixed Contexts
OCP Awardee
FYP Student
Min-Yen Kan
Associate Professor
WING lead; interests include Digital Libraries, Information Retrieval and Natural Language Processing.