When Models Edit Too Much: On the Fidelity of Minimal Code Edits
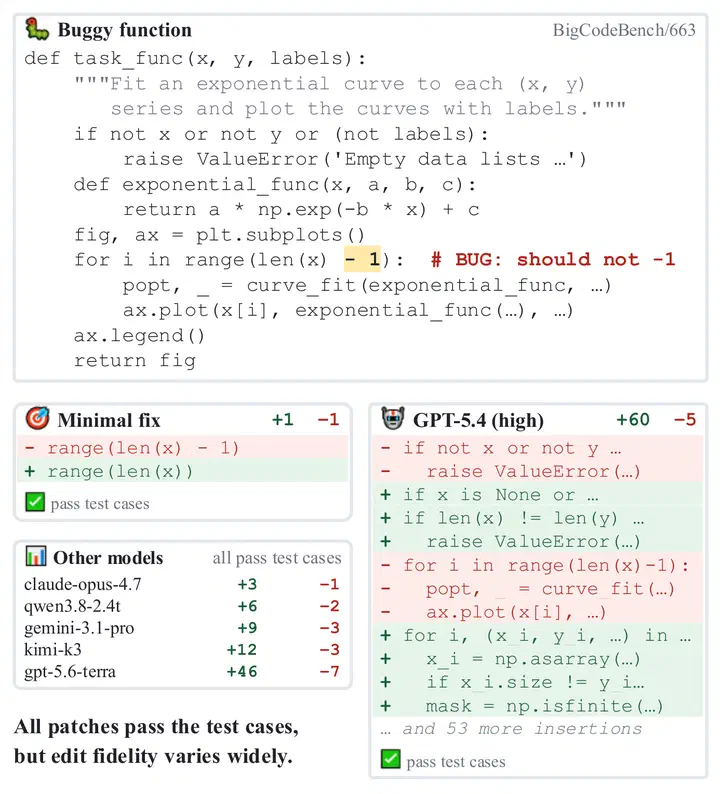 Every patch passes the tests, but edit fidelity varies widely.
Abstract
Large language models (LLMs) are increasingly used to edit existing code, but correctness alone is not enough: useful repairs should also be minimal, reviewable, and faithful to the original implementation. We study over-editing, the tendency of a model to rewrite code beyond what is required to fix a bug. We construct an evaluation framework from 400 BigCodeBench problems by injecting controlled AST-level corruptions into reference solutions, giving each repair task a known minimal patch. Across frontier LLMs, over-editing is widespread even among strong models like GPT-5.5: high Pass@1 can coexist with unnecessarily large edits and added cognitive complexity. A preservation instruction substantially reduces this behavior, lowering average excess Levenshtein distance from 0.195 to 0.131, reducing added cognitive complexity by 26.6%, and increasing Pass@1 by 2.3 points. However, these gains do not simply follow from a larger reasoning budget or larger models. We next ask whether minimal editing can be learned directly during post-training. We observe that supervised fine-tuning overfits to seen corruption patterns, whereas reinforcement learning gives the best out-of-domain edit-fidelity and performance-retention trade-off. These results position edit fidelity as a distinct axis of code-repair quality and show that it can be measured and learned.
Tongyao Zhu
IPP Doctoral Student (Jan ‘23; SEA)
Co-Supervised by Qian Liu.
Research Achievement Award (RAA, ‘25)
PhD Candidate January 2023 Intake
Wei Hern Lim
FYP Student (Aug ‘25) Thesis: When Models Edit Too Much: On the Fidelity of Minimal Code Edits
OUR Prize Awardee
FYP Student
Min-Yen Kan
Associate Professor
WING lead; interests include Digital Libraries, Information Retrieval and Natural Language Processing.